Get your data in
Load five CSV files and a live weather forecast into Keboola Storage with the HTTP data source connector, straight from their URLs.
Data arrives split across files that cannot answer a question on their own. Here it is five: a summer of sales, and four small tables that say what the sales mean (which café, which product, who was on shift, what the weather was). Apart, the sales file can plot a summer but cannot say what any day was. This page gets all five into Storage, then adds the one table you do not have: next week’s weather, fetched live from a public forecast API. The next page joins them.
Where you are: you have a project, and Storage is empty. When you finish: six tables in Storage and two connector configurations you can re-run.
Before you start
You need
- A Keboola project. No project yet? Get a project.
Depending on the tab you use
- Prompt tab: Kai, the Kai Agent button in the project's top bar, on supported stacks. The first time, an organization admin switches it on; see Get started with Kai.
- UI tab: only a browser.
- CLI / API tab: kbagent, connected to your project with write access.
Three ways to do this, one page. They are alternatives, not steps. Prompt is what you paste into Kai; UI is the same task click by click, for when you want to see where each setting lives; CLI / API is the same task from a terminal, with the raw request beside it. Pick one tab and carry on; your choice follows you to the next page.
Kai asks before it changes anything: expect one approval dialog per object it creates, showing the exact configuration it is about to write. Questions that only read do not ask. If confirming each one gets tiring, pre-approve tools in tool permissions. The chat's plan mode button is a different thing: Kai writes the steps down and asks you to approve the plan before it starts, and then still asks for each change. Use it when you want to read the plan first, not to save clicks.
If a step builds something other than what this page describes, say so in the same chat; it edits what it made. Nothing here is one-way.
The sample data
Section titled “The sample data”Five tables about a fictional café chain, Boolabean: six cafés in six Czech cities, an 18-item menu, one summer of sales, the roster for every café and day, and the weather each café had that day. The chain, the sales and the rosters are invented for this guide, with a summer of weather to match. Only the forecast is real, and it is live.
| Table | File | Rows |
|---|---|---|
| stores | /getting-started/boolabean/stores.csv | 6 |
| products | /getting-started/boolabean/products.csv | 18 |
| sales | /getting-started/boolabean/sales.csv | 9,761 |
| staffing | /getting-started/boolabean/staffing.csv | 552 |
| weather_daily | /getting-started/boolabean/weather_daily.csv | 552 |
Each table is half a story. A sales row names its café as S02 and its product as P07; the
roster knows how many people were on shift but not what they sold; the weather table knows it
rained but not what that did to the queue.
The sixth table is not one of the sample files. Open-Meteo publishes a free forecast API with no account and no key, and one request returns the next seven days for all six cafés at once as CSV:
https://api.open-meteo.com/v1/forecast?latitude=50.0755,49.1928,49.8352,49.7475,49.5938,50.7663&longitude=14.4426,16.6083,18.2833,13.3776,17.2509,15.0562&daily=temperature_2m_max,precipitation_sum&timezone=Europe%2FPrague&format=csvThe six coordinate pairs are the cafés in store_id order, so location_id 0 in the answer is
S01 and 5 is S06. The file has a shape the connector has to be told about: seven lines of
metadata about the locations, a blank line, and then the real header row. Loaded as it comes, it
is 42 rows: seven days for six cafés.
How loading works
Section titled “How loading works”Data gets into Keboola through data source connectors, components that fetch from a source on demand or on a schedule. There are hundreds of them: databases, APIs, ad platforms, cloud drives. They differ in how they authenticate and what they can fetch, but they all end the same way: rows in a Storage table.
You will use the HTTP connector, which downloads CSV files from a URL. It is the simplest one that still behaves like a real connector: it can be re-run, scheduled, and dropped into a flow, which is what Make it run every morning depends on.
One configuration can fetch many files, so the five sample files go into a single configuration with five rows. The forecast gets a configuration of its own, because it lives on a different host and because the flow will want to refresh it every morning while the history stays as it is.
Set it up
Section titled “Set it up”Setting up a data source connector is one of the things Kai does (Integration Setup). Open Kai Agent in the top bar and ask for the whole first configuration at once:
Load these five CSV files into Storage as one HTTP data source configuration called "Boolabeansales", one configuration row per file, each table named after its file:
https://help.keboola.com/getting-started/boolabean/stores.csvhttps://help.keboola.com/getting-started/boolabean/products.csvhttps://help.keboola.com/getting-started/boolabean/sales.csvhttps://help.keboola.com/getting-started/boolabean/staffing.csvhttps://help.keboola.com/getting-started/boolabean/weather_daily.csv
Run it, then tell me the row count of each of the five tables.
Expect seven approval dialogs: the configuration, one per row, and the run. Kai reads the header of each file itself, so the tables come out with the files’ column names.
Check: Kai reports five tables with 6, 18, 9,761, 552 and 552 rows, and the configuration’s Rows list shows five entries. Then, in the same chat, the forecast:
Add a second HTTP data source configuration called "Boolabean forecast" that loads this one URLinto a table called forecast:
https://api.open-meteo.com/v1/forecast?latitude=50.0755,49.1928,49.8352,49.7475,49.5938,50.7663&longitude=14.4426,16.6083,18.2833,13.3776,17.2509,15.0562&daily=temperature_2m_max,precipitation_sum&timezone=Europe%2FPrague&format=csv
It is open-meteo's CSV export: seven lines of metadata, a blank line, then the header row, then42 data rows. Load only the data rows and name the columns location_id, time,temperature_2m_max and precipitation_sum. Run it, then tell me how many rows the forecast tablehas.
Kai inspects the file, skips the nine leading lines and names the four columns as asked, rather
than keeping the header’s temperature_2m_max (°C). Three approvals this time.
Check: a forecast table with 42 rows and the columns location_id, time,
temperature_2m_max and precipitation_sum. If Kai built something else, delete it and switch to
the UI tab. The extra minutes pay for themselves, because the rest of the guide
assumes you have seen where a configuration and its rows live.
Create the configuration
-
Open Components and search for
HTTP. Pick the plain HTTP (Data Source), the one described as Downloading CSV files from any HTTP, and HTTPS URL, and click Add Component (the card says Create Configuration instead once the component already has configurations in the project). The other match, HTTP Advanced (Beta), is a different component. Newer connectors with HTTP in the name may also appear; go by that description rather than by position in the list.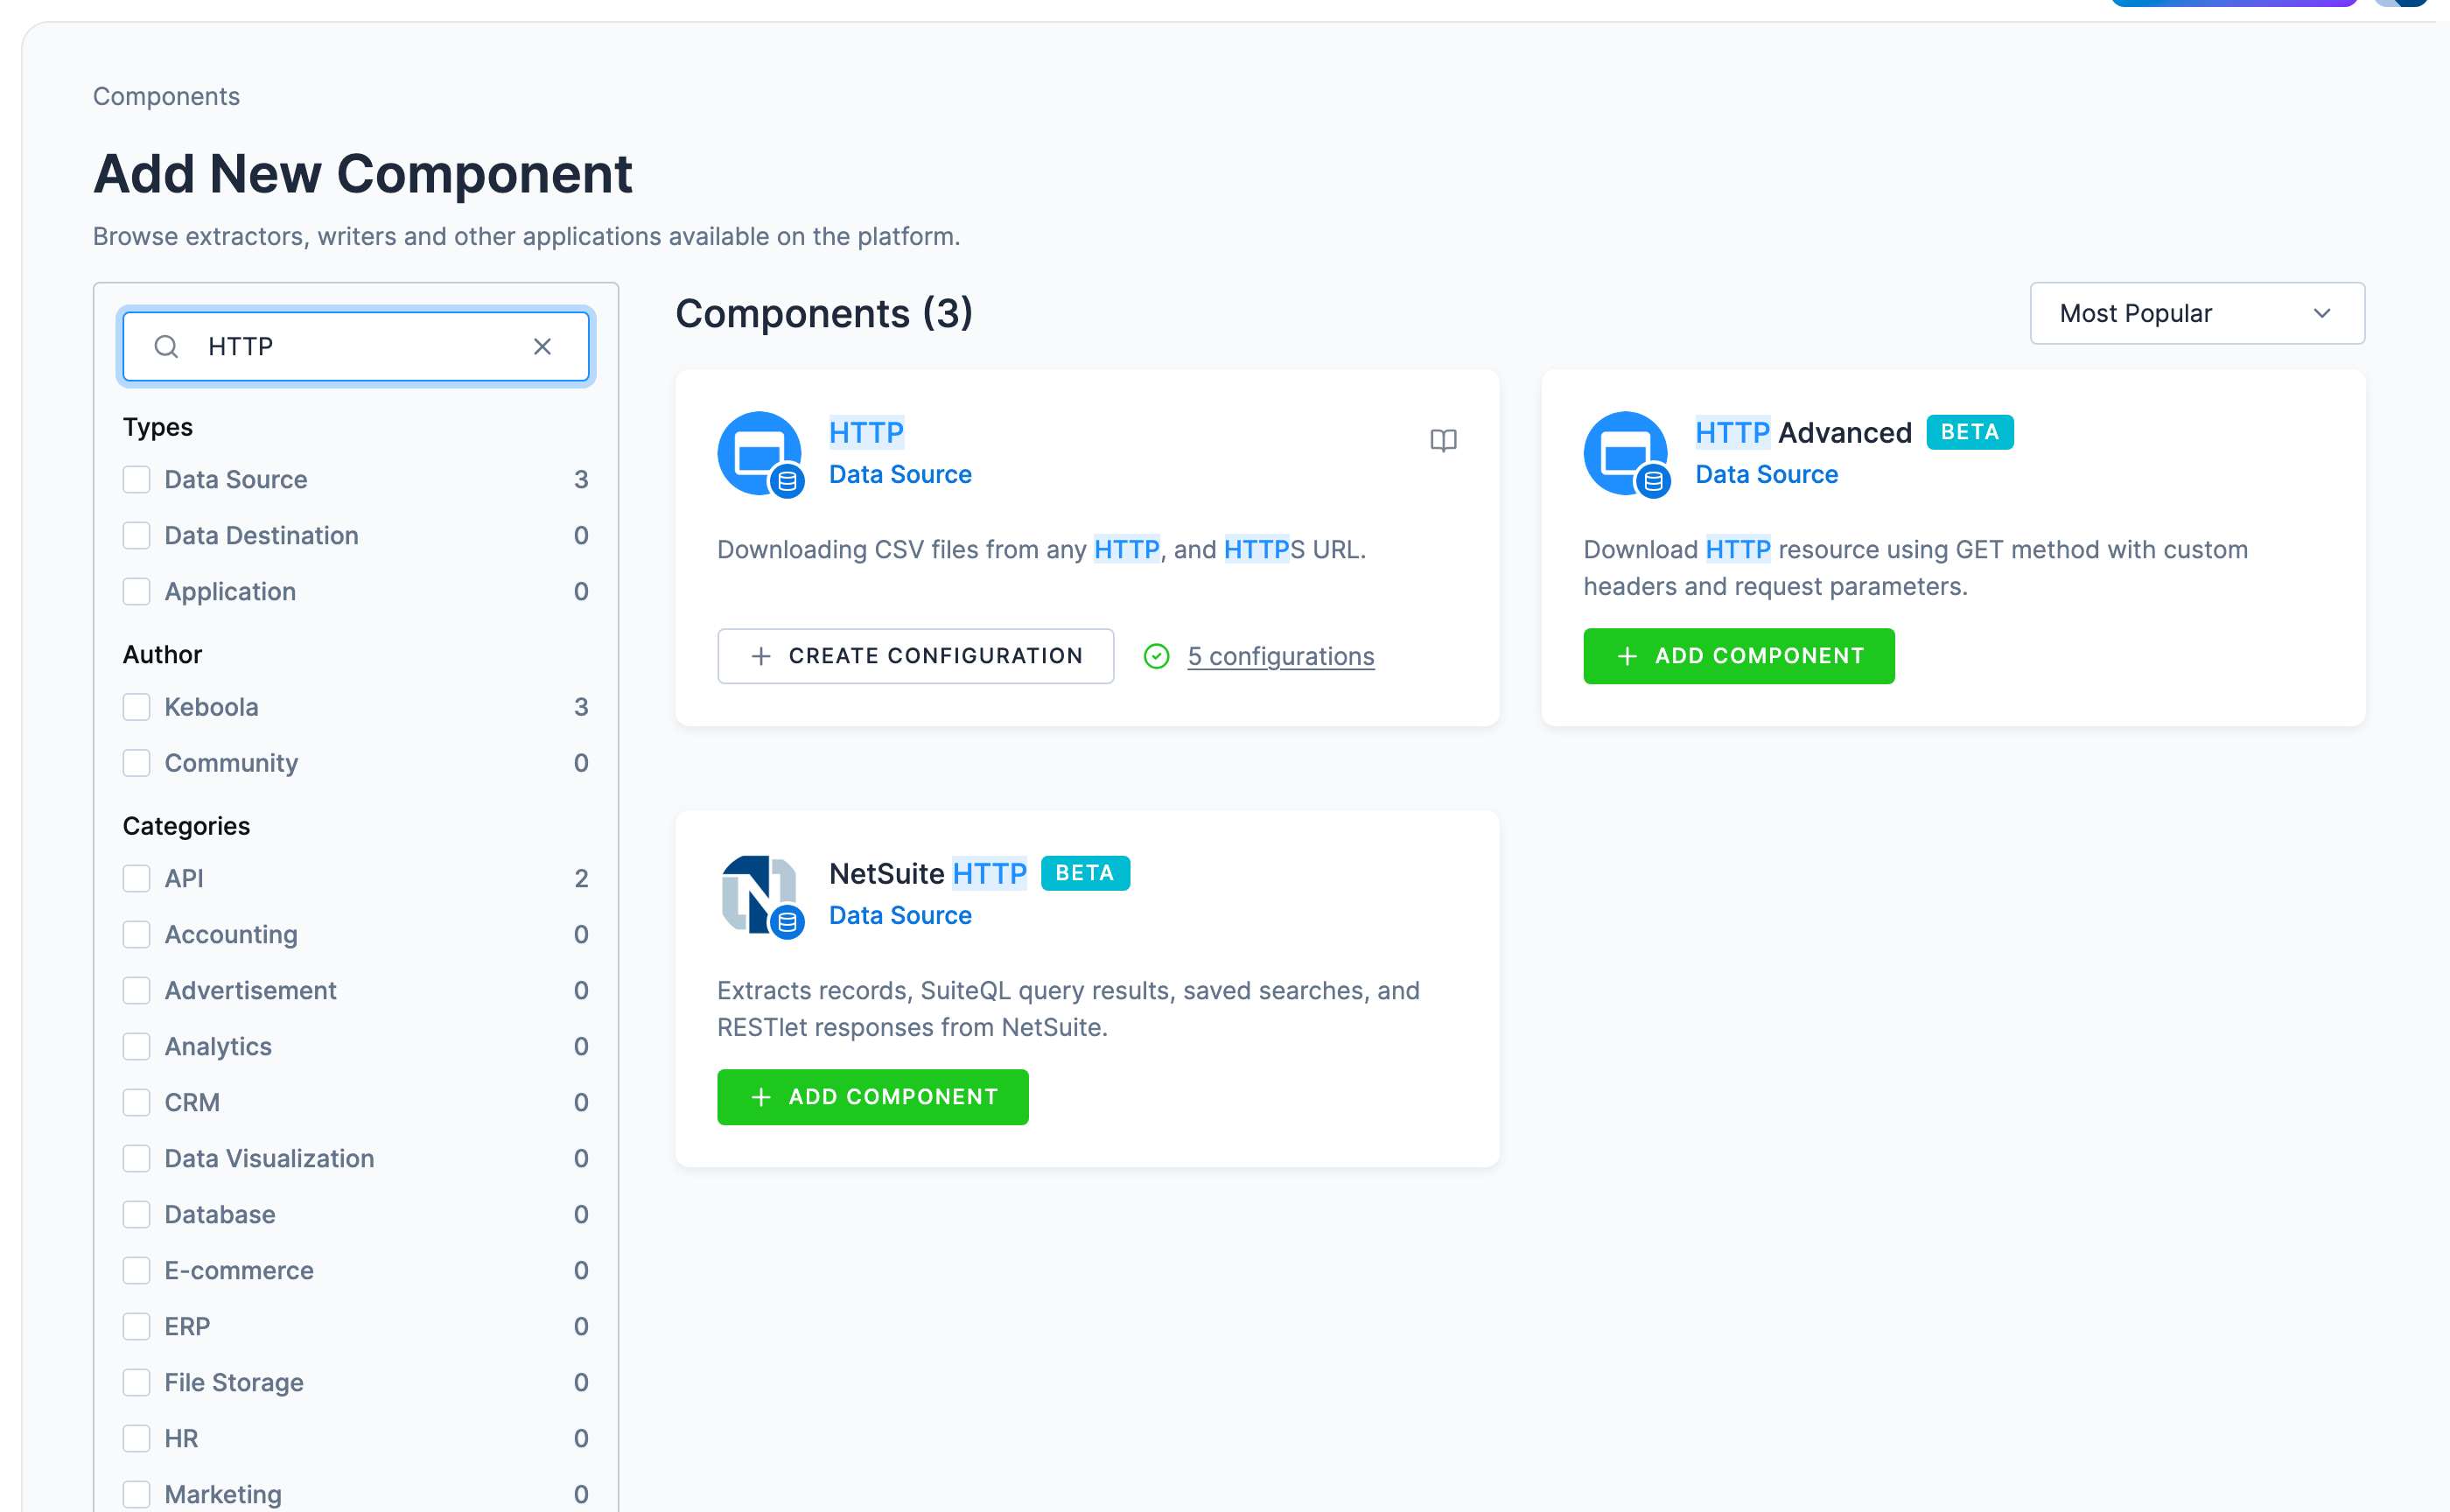
-
Choose Connect To My Data. (Use With Demo Data sets the connector up against a dataset Keboola prepared, handy for a look around, but here you want your own URL.)
-
Replace the suggested name with
Boolabean sales, add a description, and click Create Configuration. Descriptions are what keep a project readable six months later; see the best practices cheat sheet.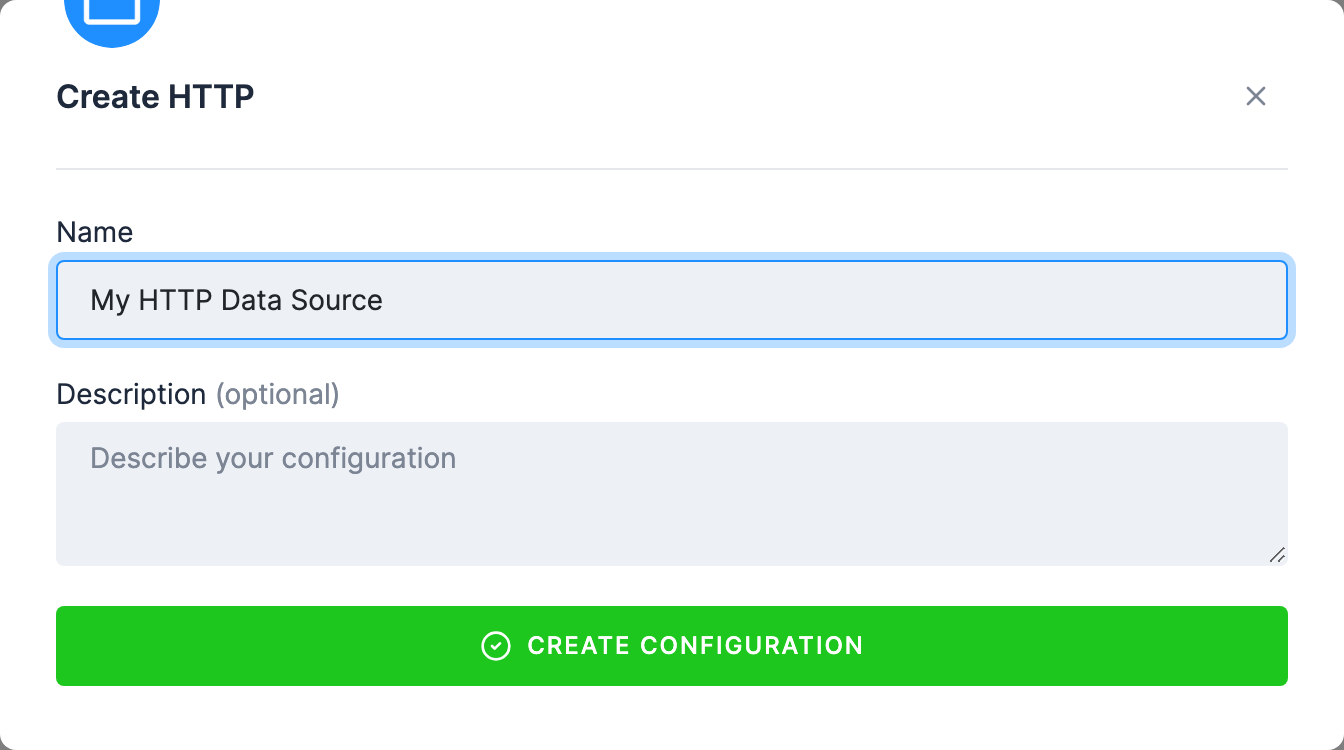
-
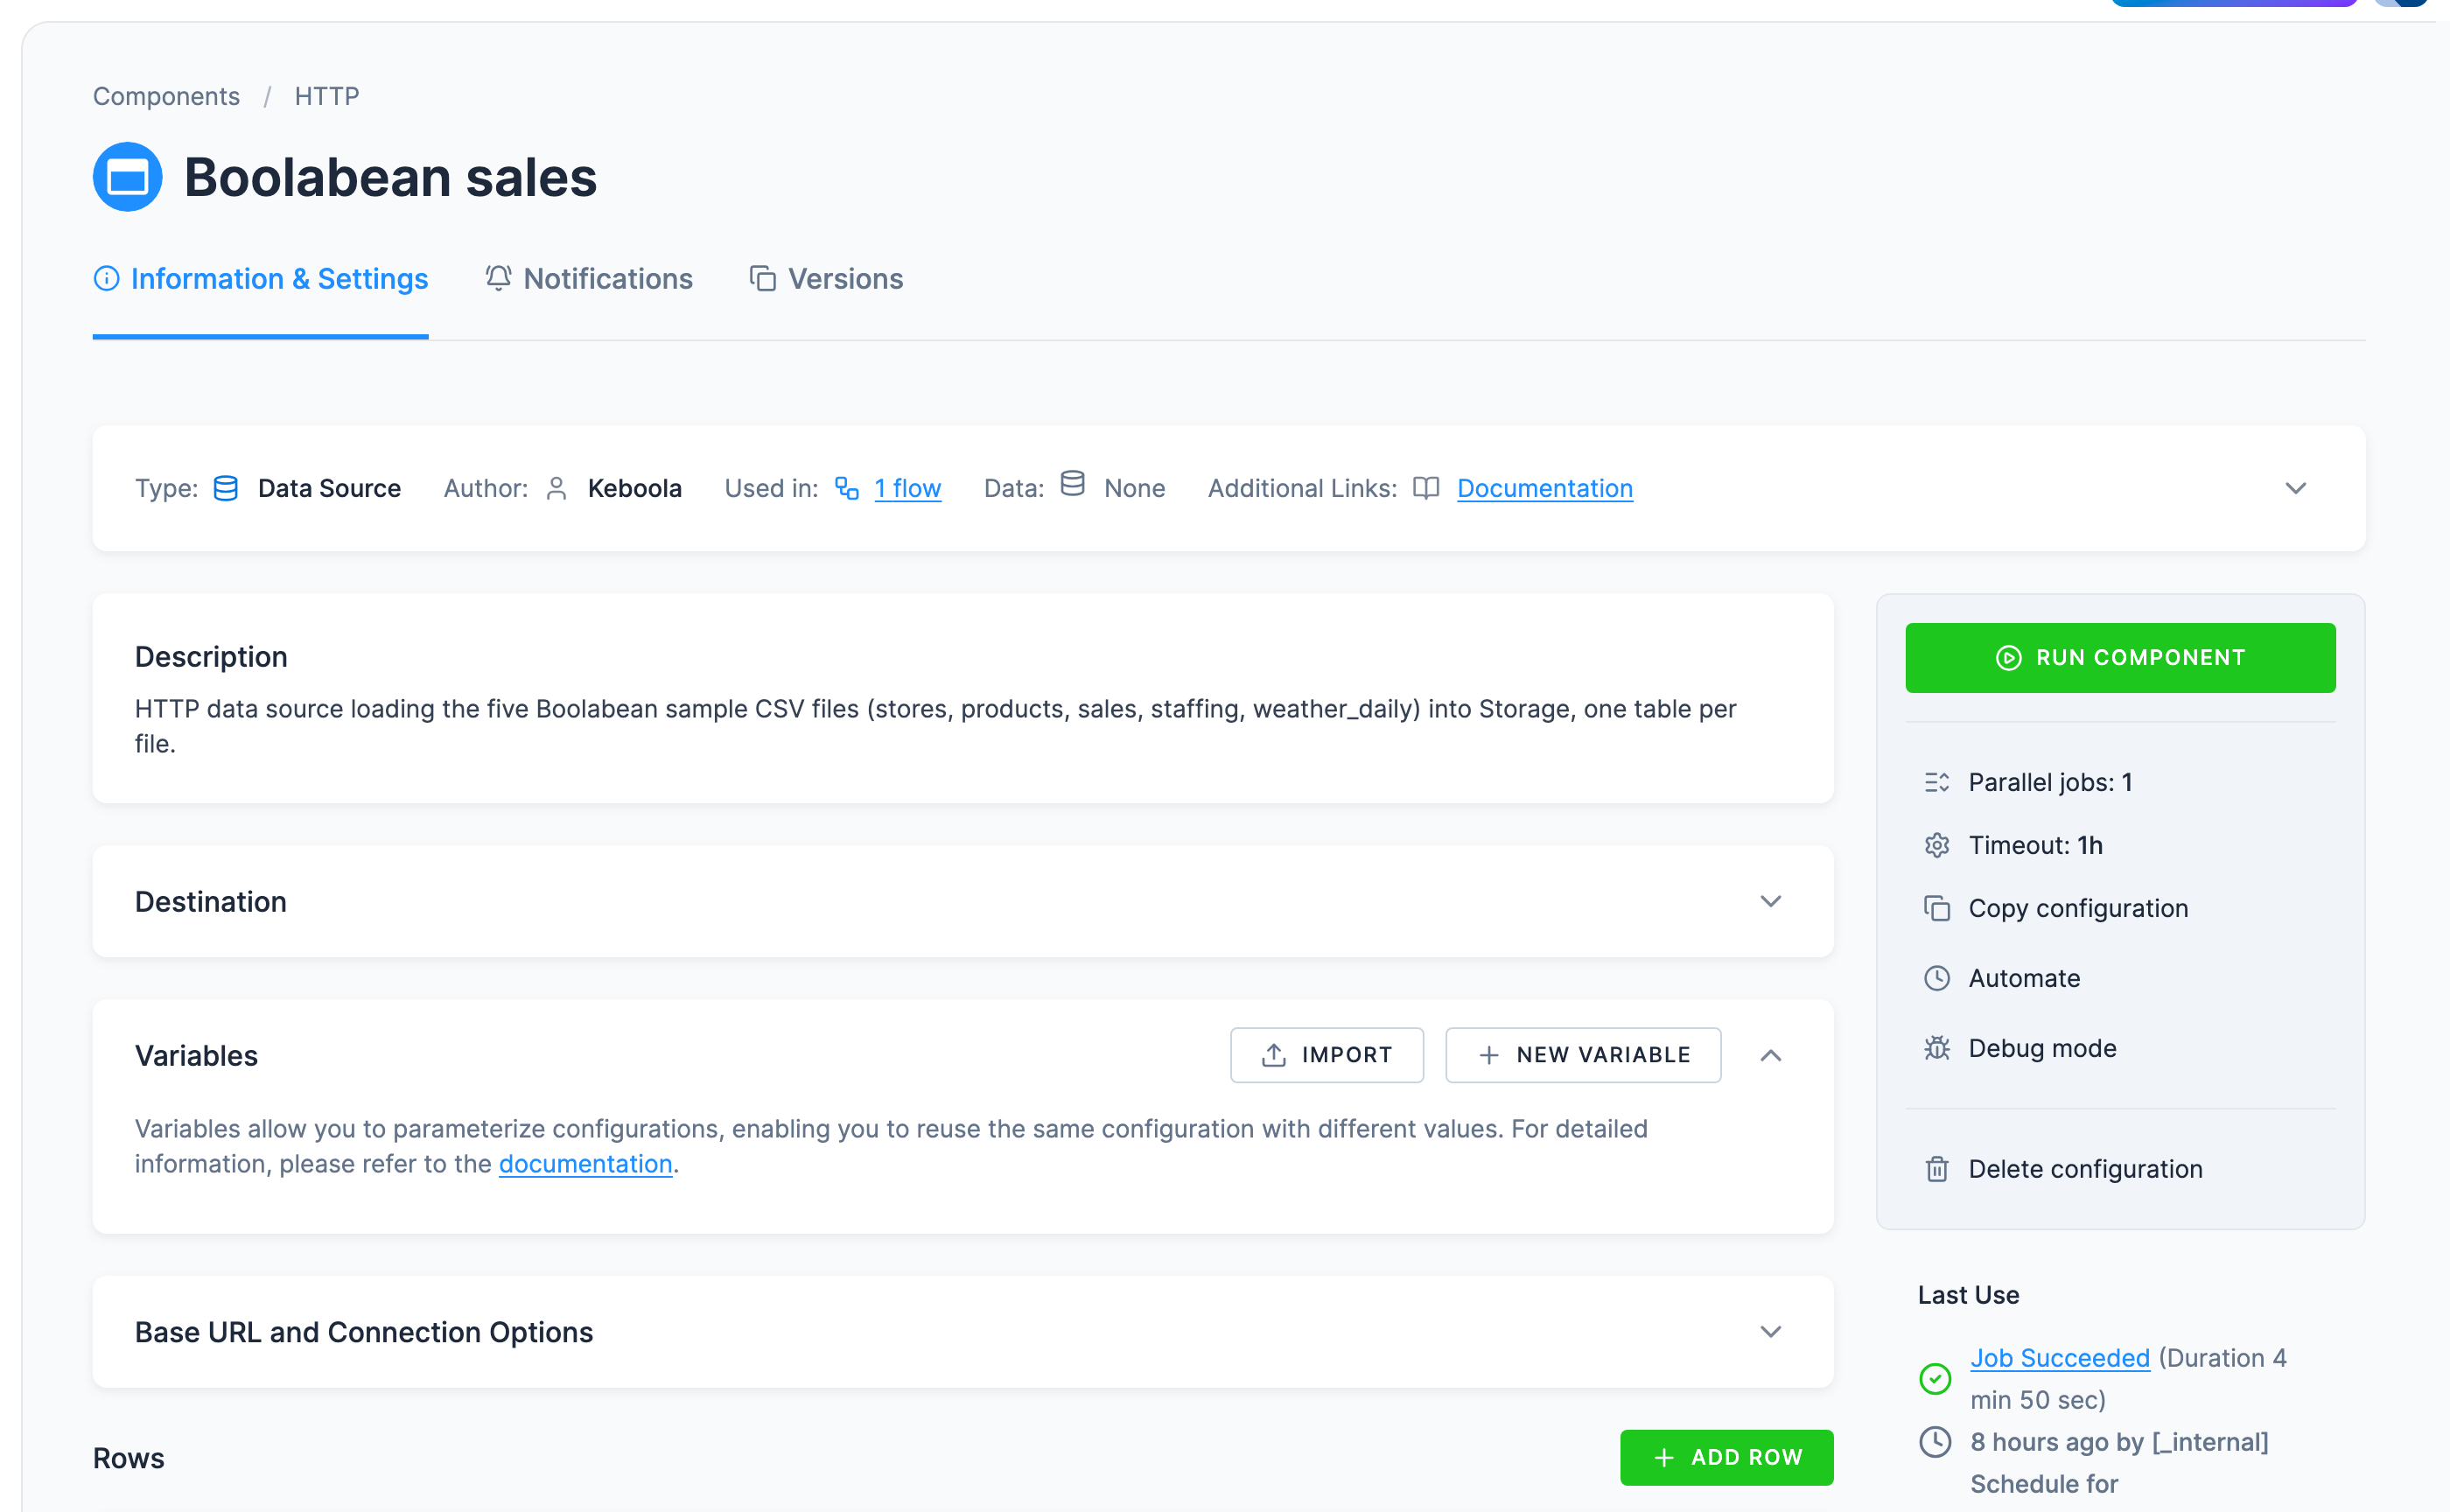
If the configuration opens with a single File URL field, switch to Advanced Mode. A new configuration may start in a simplified mode that takes one URL and nothing else: no base URL, no rows. Its own hint says as much: switch modes if you “want to load more files at once”. Use Advanced Mode, top right, and confirm. This is one-way: the button disappears afterwards, and the change is recorded on the configuration as Disable simplified mode. If you already see Base URL and Connection Options and a Rows section, you are in the right mode and there is nothing to switch.
-
Open Base URL and Connection Options and set Base URL to the folder shared by every file this configuration downloads, with its trailing slash, then click Save:
https://help.keboola.com/getting-started/boolabean/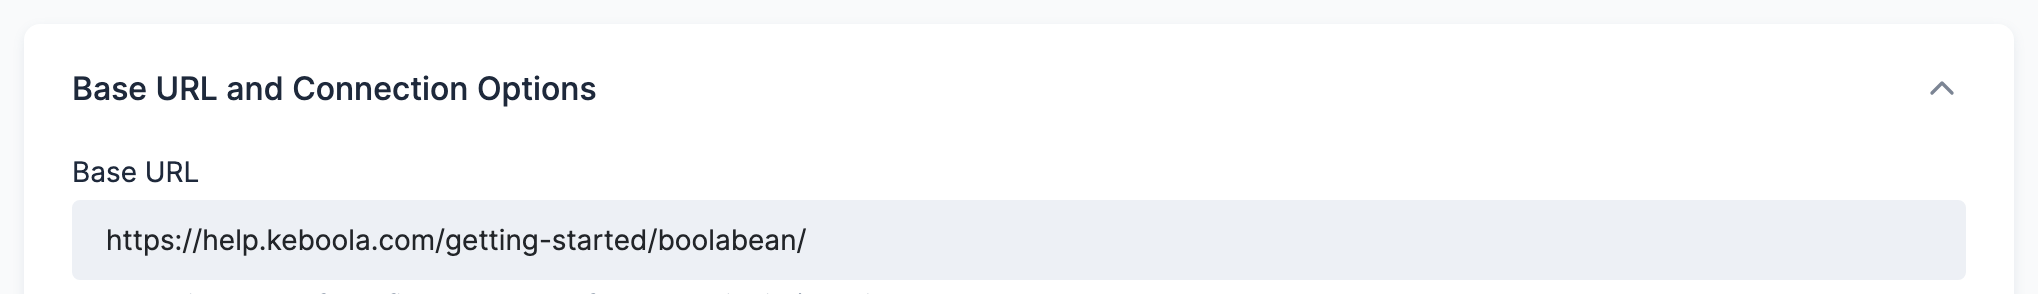
Add the five tables
Each file is a configuration row with its own path and settings, sharing the configuration’s base URL.
-
In the Rows section, click Add Row, name it
stores, and click Create. The row name becomes the Storage table name, so use exactly this spelling. -
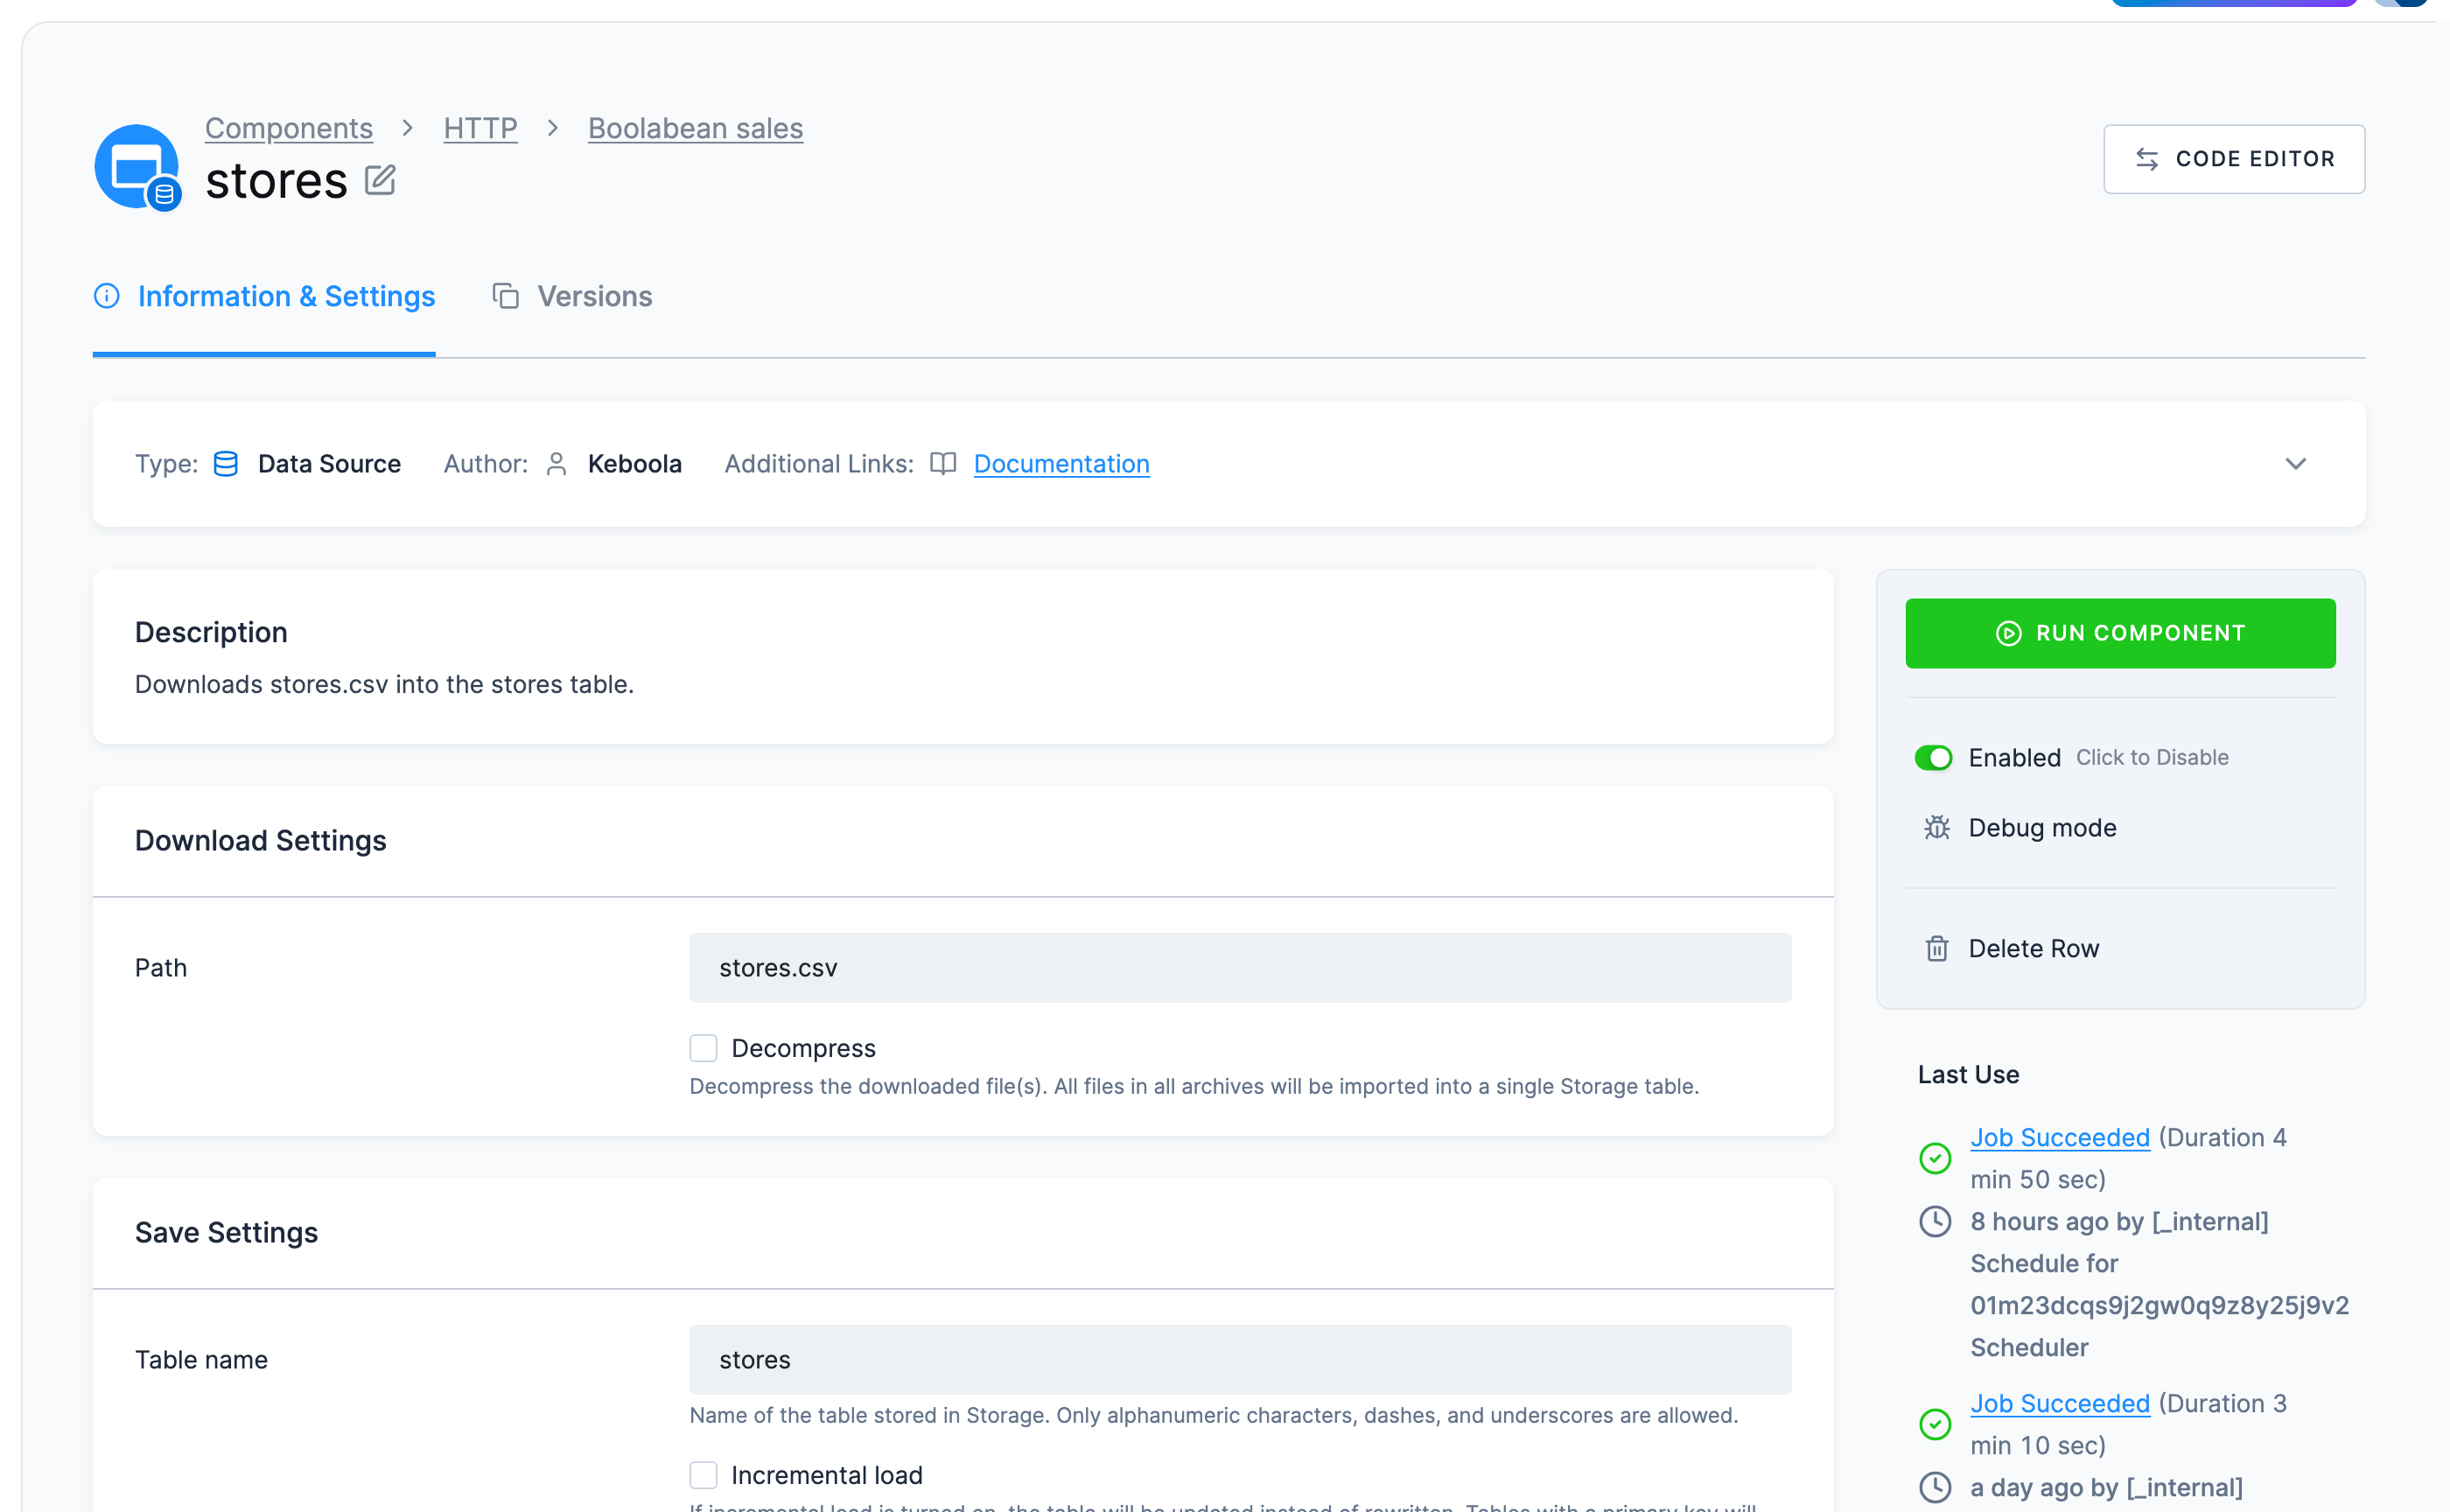
Under Download Settings, set Path to the file name, relative to the base URL:
stores.csv -
Check the rest of the row and click Save:
- Save Settings → Table name is already
stores, taken from the row name. - Delimiter
,and Enclosure"are already right for these files. - Leave Incremental load off: each run should replace the table, not append to it.
- Header & Primary Key → Read Header already says Read the header from the file(s) header, which is what you want; the sample files carry column names on the first line. Leave it alone. (The alternative, Set Header, is typing the columns yourself; the forecast below is where that becomes necessary.)
- Save Settings → Table name is already
-
Repeat steps 6 to 8 for the other four files:
Row name Path productsproducts.csvsalessales.csvstaffingstaffing.csvweather_dailyweather_daily.csv -
Back on the configuration, click Run Component and confirm with Run. One run fetches all five rows; in Jobs it may fan out into a job per row under the one you started.
Add the forecast
-
Create a second configuration the same way (steps 1 to 5), named
Boolabean forecast, with the base URLhttps://api.open-meteo.com/v1/. Add one row namedforecastand set its Path to everything after that in the forecast URL above, starting withforecast?latitude=. Save. -
The visual form cannot skip the seven metadata lines and the blank line before the header, so this row is finished in JSON. Click Code Editor at the top of the row, replace the
processorsblock with the one below, and save:"processors": {"after": [{ "definition": { "component": "keboola.processor-move-files" },"parameters": { "direction": "tables", "folder": "forecast" } },{ "definition": { "component": "keboola.processor-skip-lines" },"parameters": { "lines": 9 } },{ "definition": { "component": "keboola.processor-create-manifest" },"parameters": { "delimiter": ",", "enclosure": "\"", "incremental": false,"primary_key": [],"columns": ["location_id", "time", "temperature_2m_max", "precipitation_sum"] } }]}Nine lines skipped, not eight: the header row goes too, and the
columnslist names the columns in its place, without the header’s unit suffixes. From now on this row opens in the code editor, and the Visual Editor button stays disabled with the note Can’t close the code editor, the configuration is not compatible. That is expected.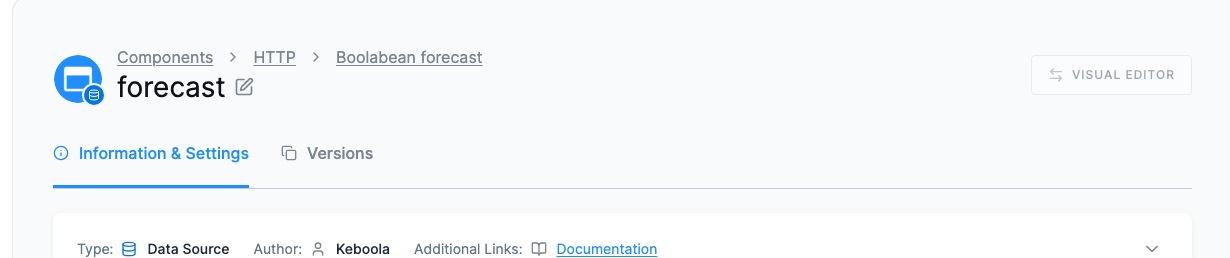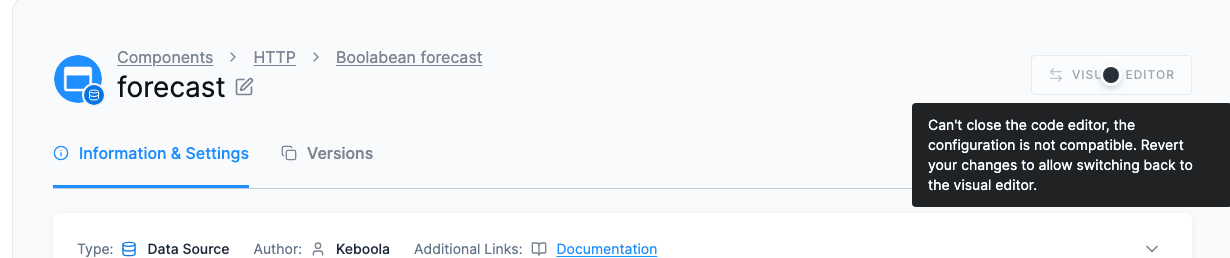
-
Run Component on this configuration as well.
Every click above is an API call underneath, and kbagent is the same calls from a terminal.
This tab needs two things the other two do not. kbagent
installed and pointed at your project once with kbagent project add,
which stores the connection under an alias. The examples use docs-demo, substitute yours. And
for the raw-request examples, two values you read off your own project: <your-stack> is the host
you sign in at, the part after https:// in the browser’s address bar (for example
connection.europe-west3.gcp.keboola.com), and $KBC_TOKEN is a Storage API token from
Users & Settings → API Tokens.
Create the configuration
The configuration itself carries only the base URL. --no-files says “just create it remotely”,
and --dry-run shows the request and validates it against the component’s schema without creating
anything:
kbagent config new --project docs-demo --component-id keboola.ex-http --name "Boolabean sales" --push --no-files --configuration '{"parameters":{"baseUrl":"https://help.keboola.com/getting-started/boolabean/"}}'It prints the new configuration ID; keep it for the next two commands. The same call as a raw request, if you would rather see it:
curl -X POST "https://<your-stack>/v2/storage/components/keboola.ex-http/configs" -H "X-StorageApi-Token: $KBC_TOKEN" -F "name=Boolabean sales" -F 'configuration={"parameters":{"baseUrl":"https://help.keboola.com/getting-started/boolabean/"}}'Add the five tables
Each file is a row on that configuration. The row’s JSON is the path, plus the processors that put the result in a table of the same name and read the column names from the file’s header: the same three settings the UI tab fills in by hand:
kbagent config row-create --project docs-demo --component-id keboola.ex-http --config-id <config-id> --name stores --configuration '{"parameters":{"path":"stores.csv"},"processors":{"after":[{"definition":{"component":"keboola.processor-move-files"},"parameters":{"direction":"tables","folder":"stores"}},{"definition":{"component":"keboola.processor-create-manifest"},"parameters":{"delimiter":",","enclosure":"\"","incremental":false,"primary_key":[],"columns_from":"header"}},{"definition":{"component":"keboola.processor-skip-lines"},"parameters":{"lines":1}}]}}'Repeat for products, sales, staffing and weather_daily, changing the name, the path and
the folder together. Then run the configuration and wait for the job:
kbagent job run --project docs-demo --component-id keboola.ex-http --config-id <config-id> --waitAdd the forecast
The same two commands. The difference is the row’s processors: nine lines skipped instead of one, and the four column names given explicitly instead of read from a header.
kbagent config new --project docs-demo --component-id keboola.ex-http --name "Boolabean forecast" --push --no-files --configuration '{"parameters":{"baseUrl":"https://api.open-meteo.com/v1/"}}'The row’s JSON is long, and --configuration takes @file, so put it in one:
{ "parameters": { "path": "forecast?latitude=50.0755,49.1928,49.8352,49.7475,49.5938,50.7663&longitude=14.4426,16.6083,18.2833,13.3776,17.2509,15.0562&daily=temperature_2m_max,precipitation_sum&timezone=Europe%2FPrague&format=csv" }, "processors": { "after": [ { "definition": { "component": "keboola.processor-move-files" }, "parameters": { "direction": "tables", "folder": "forecast" } }, { "definition": { "component": "keboola.processor-skip-lines" }, "parameters": { "lines": 9 } }, { "definition": { "component": "keboola.processor-create-manifest" }, "parameters": { "delimiter": ",", "enclosure": "\"", "incremental": false, "primary_key": [], "columns": ["location_id", "time", "temperature_2m_max", "precipitation_sum"] } } ] }}Nine lines skipped, not eight: the header goes too, and columns names the four columns in its
place, without the header’s unit suffixes.
kbagent config row-create --project docs-demo --component-id keboola.ex-http --config-id <forecast-config-id> --name forecast --configuration @forecast-row.jsonkbagent job run --project docs-demo --component-id keboola.ex-http --config-id <forecast-config-id> --waitCheck: the tables and their row counts, without leaving the terminal. Without --bucket-id
it lists every table in the project, which is how you find the bucket the connector created:
kbagent storage tables --project docs-demo --bucket-id in.c-keboola-ex-http-<config-id>kbagent storage table-detail --project docs-demo --table-id in.c-keboola-ex-http-<config-id>.salesCheck it worked
Section titled “Check it worked”Watch it in Jobs. The rows of the first configuration are fetched in turn, so expect a couple of minutes for all five; the forecast takes seconds.
Then open Storage. Data lives in buckets, and each bucket holds tables. Each connector
configuration created a bucket of its own, named after the component plus the configuration’s
ID, like keboola-ex-http-01m20b1fwj3px5x6bzzckeb81a, shown with an IN badge. One holds
stores, products, sales, staffing and weather_daily; the other holds forecast.
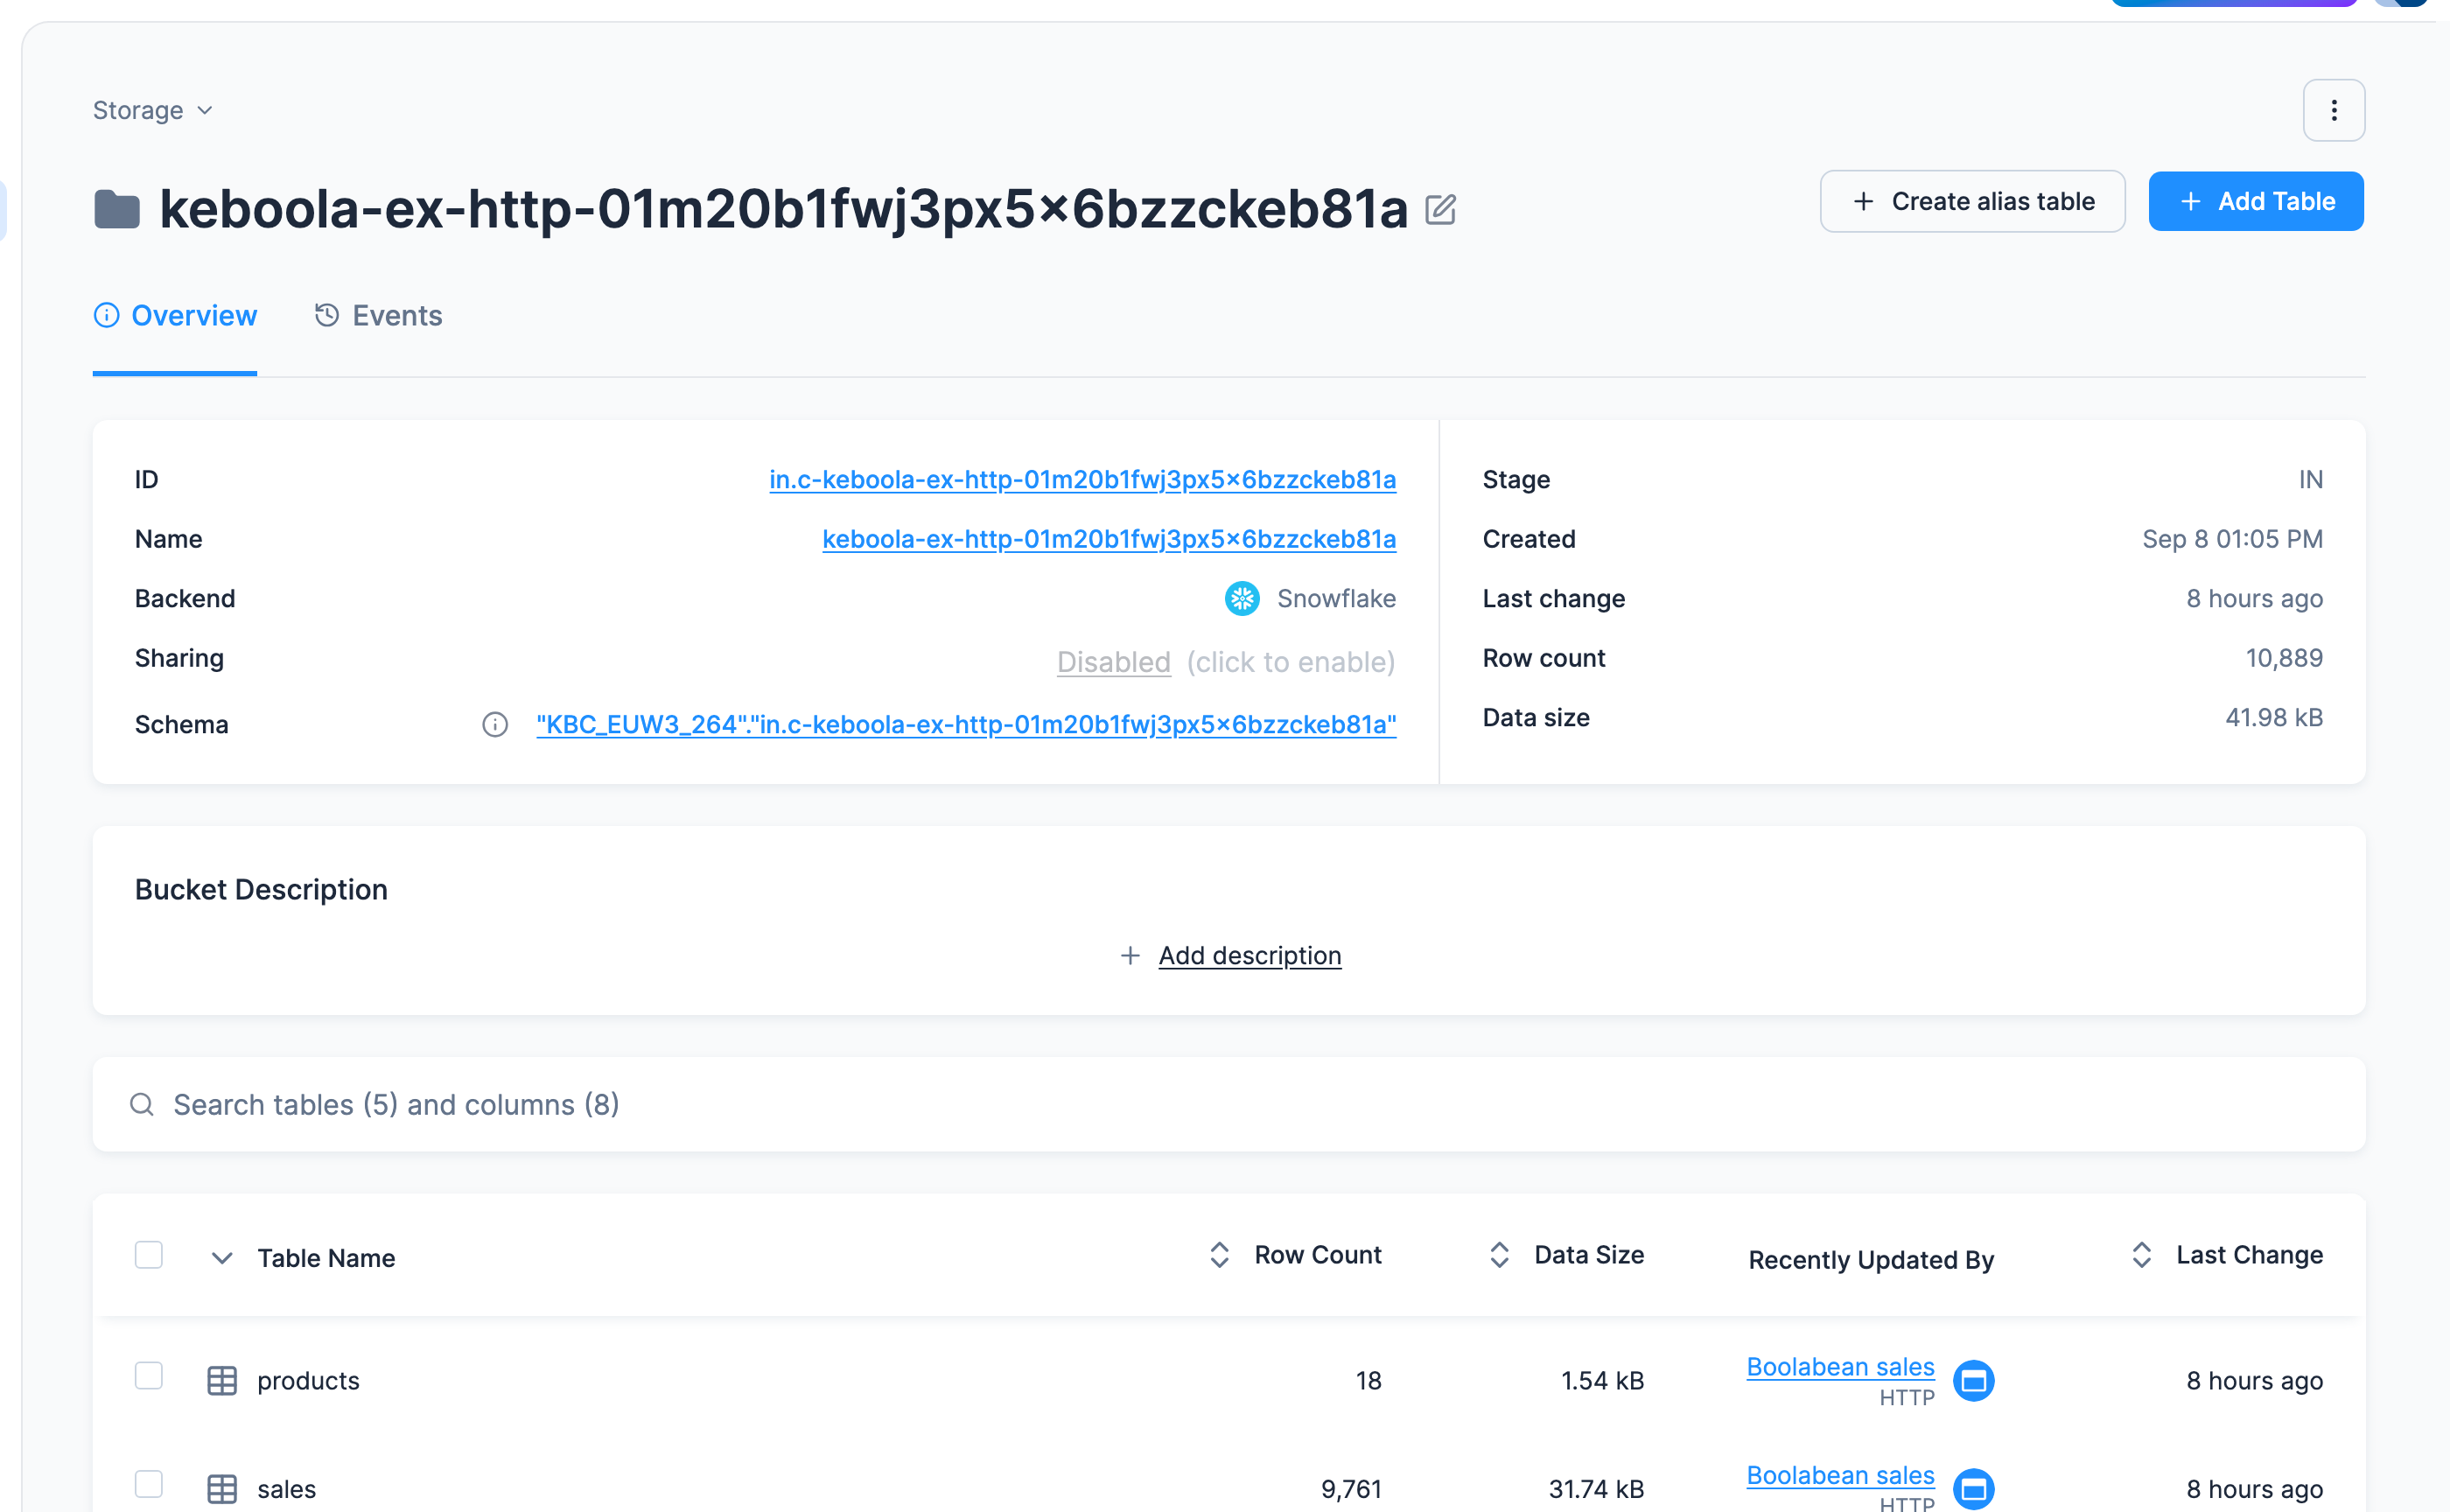
Click a table and open its Data Sample tab to see the real contents. sales should have 9,761
rows with the columns date, store_id, product_id, units and revenue_czk; stores 6,
products 18, staffing and weather_daily 552 each; forecast 42, with seven distinct dates
and location_id running 0 to 5. If that matches, this step is done.
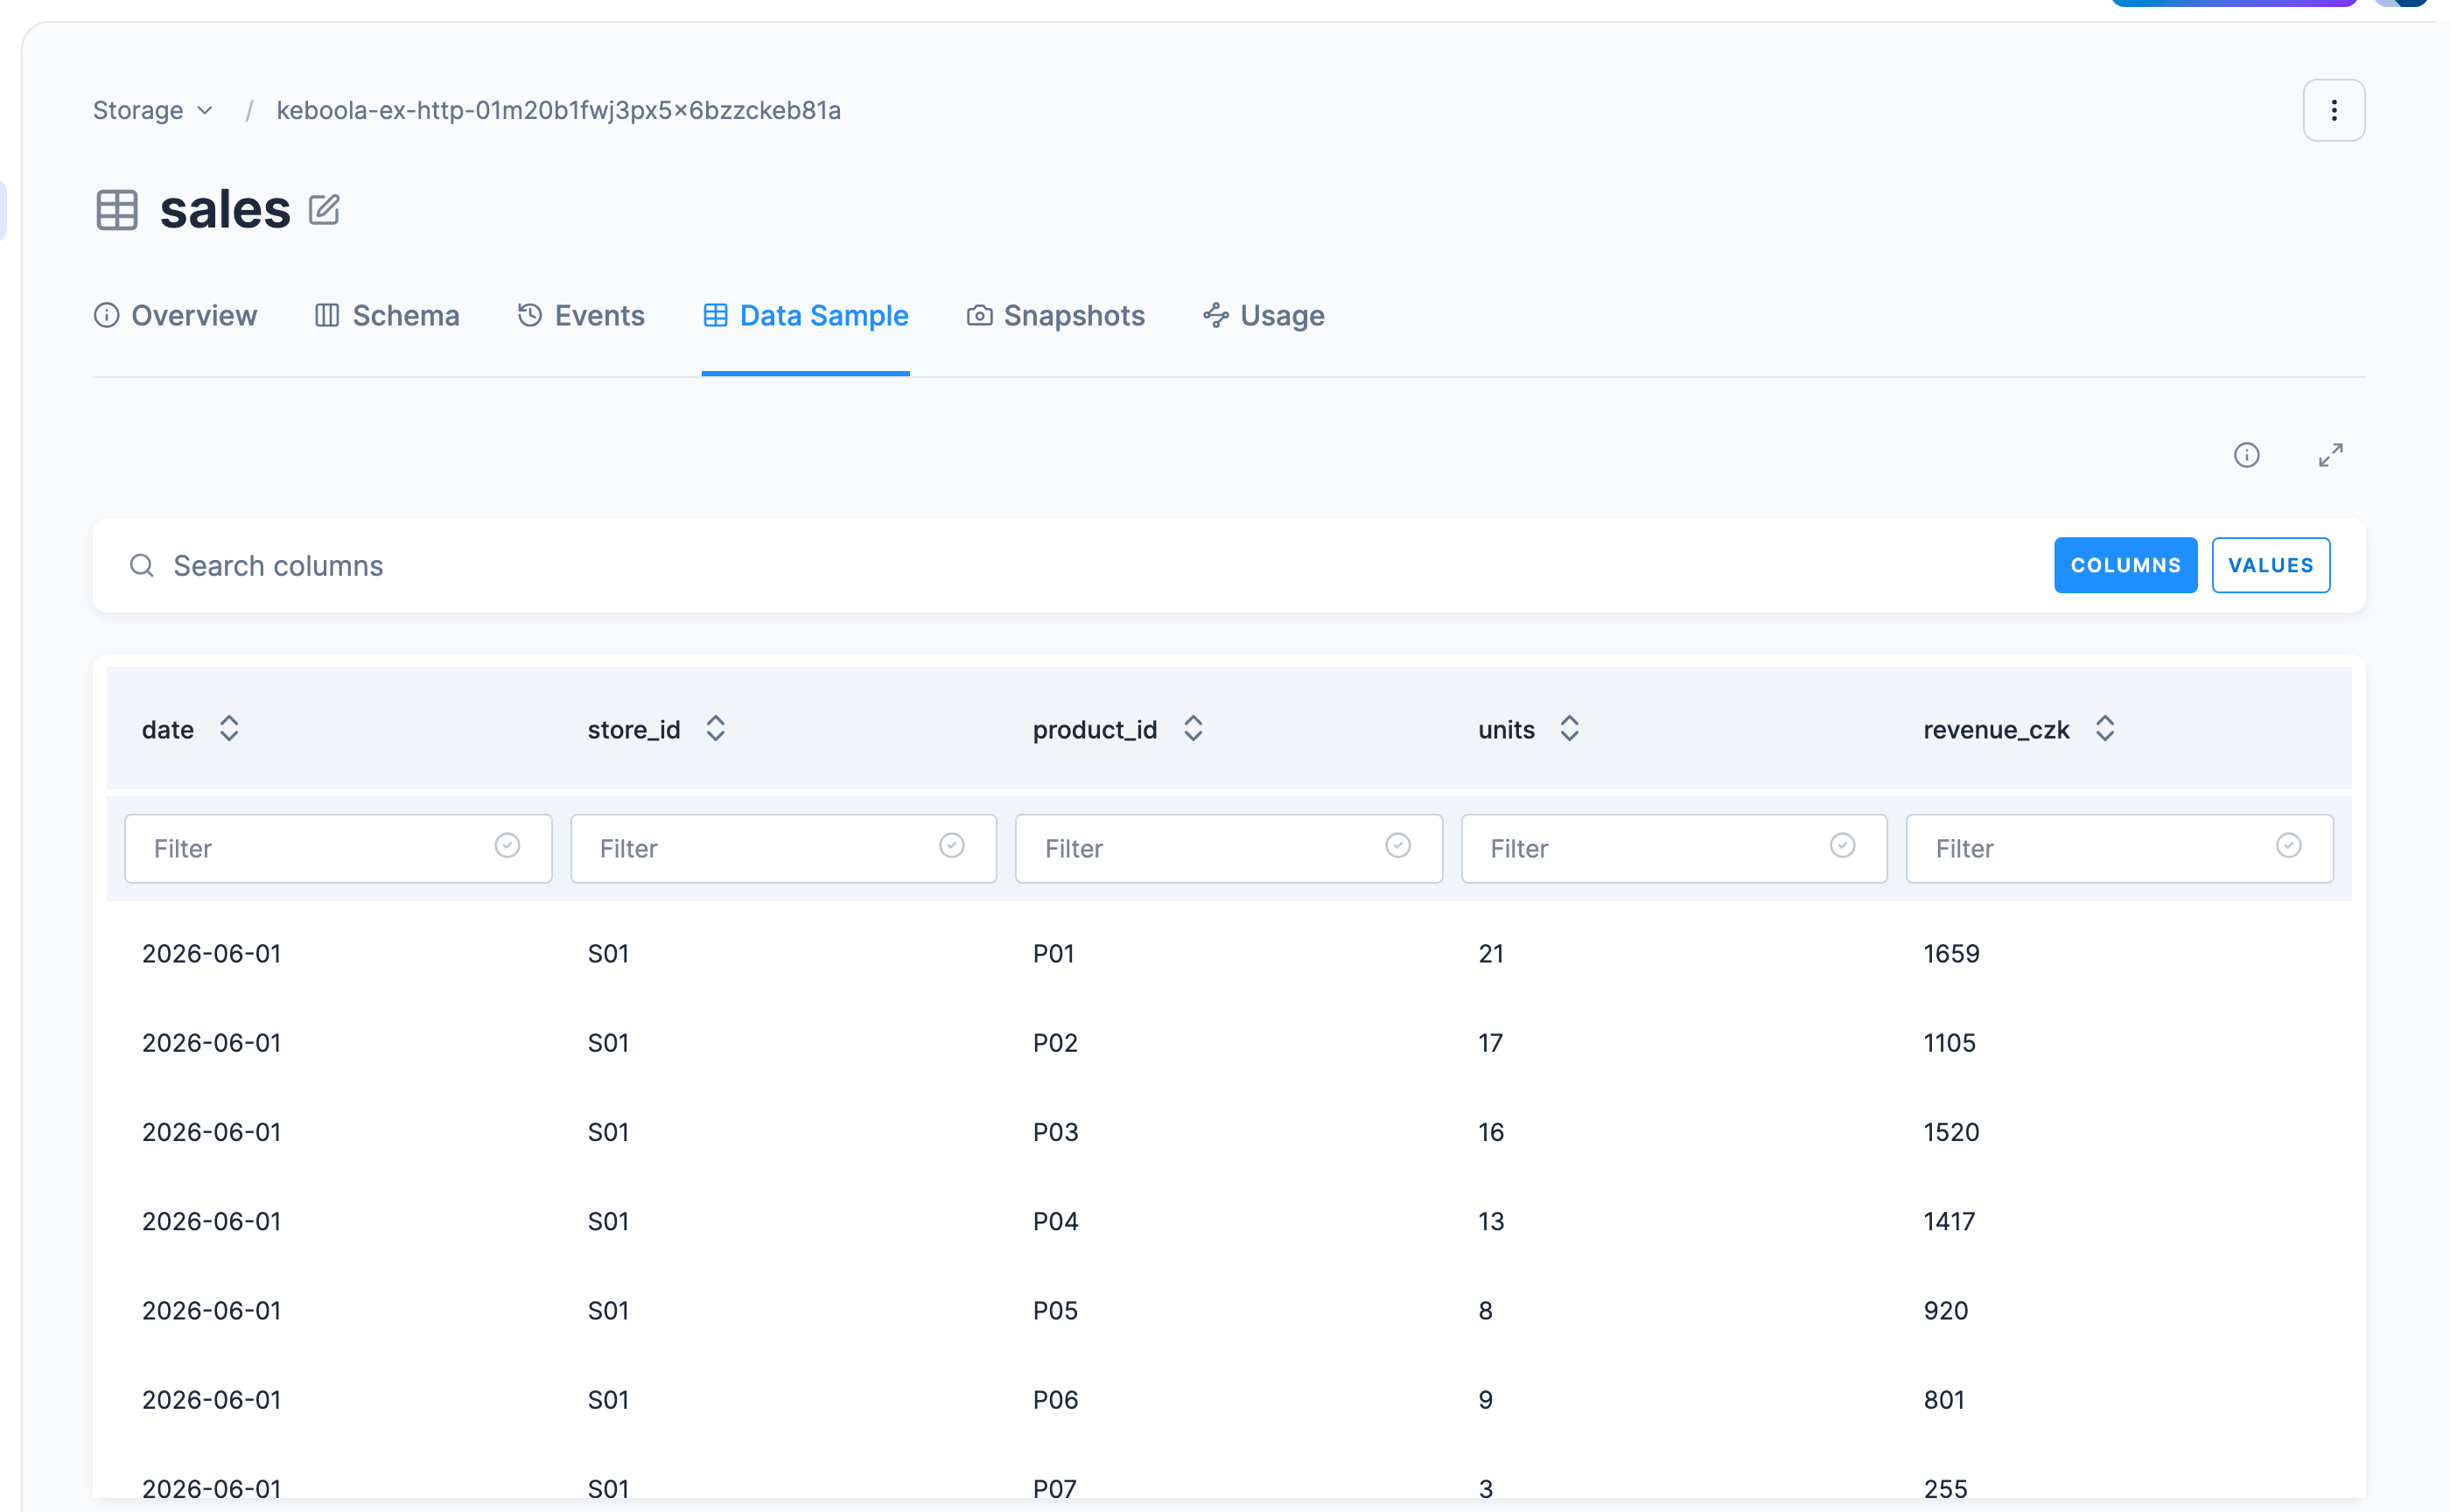
One thing to notice in the sample: every column, units and temp_max_c included, arrived as
text. The connector does not guess types, and Storage keeps what it was given. The next page casts
them before it does arithmetic, and that is why.
If it goes wrong
Section titled “If it goes wrong”- The job fails with a 404. Base URL and path are simply concatenated. With the base URL
ending in a slash and the path a bare file name,
https://help.keboola.com/getting-started/boolabean/stores.csvis right; a slash on both sides gives a double slash and a slash on neither runs the folder into the file name. Open the full URL in a browser to see whether the file is really there.
- Every row arrives as one column. The Delimiter setting does not match the file. These files are comma-separated.
- The first data row is missing, or columns are called
col_1. Wrong header option: set Read Header back to Read the header from the file(s) header. - The table is empty but the job succeeded. The URL returned an HTML error page instead of a CSV. Open it in a browser to see what actually comes back.
- The forecast has 43 rows, and one of them says
timein thetimecolumn. The skip count is one short and the header was loaded as data. It should be 9 with named columns, or 8 with Read the header and the header’s own names, unit suffixes included. - You want the five files fetched at the same time. Raise Parallel jobs on the configuration; the connector then processes its rows concurrently.
- You would rather have Kai read the job. It has the log and the tables in front of it:
Read the last HTTP connector job and tell me what failed, then show me a sample of sales.
Going further
Section titled “Going further”Which way you load depends on how far along the project is. A public URL is the quickest way to get real data into a project you just created, which is why a proof of concept usually starts there. Production data rarely sits on one. It is behind credentials, in a database or a SaaS account, and it keeps changing, so the run you kicked off by hand becomes one that repeats on a schedule. Both side trips are this same step against a source you have to authorize first.
- Load from Google Sheets is a small reference table pulled from a spreadsheet you own, with an authorized account instead of a public URL.
- Load from a database is the pattern every database connector follows.